I am a Ph.D. student in Integrated Circuit Science and Engineering at Southern University of Science and Technology, jointly trained with Peng Cheng Laboratory. I received my B.Eng. degree in Microelectronics Science and Engineering from Southern University of Science and Technology.
My research focuses on AI acceleration, neuromorphic computing, spiking neural network training, NPU operator optimization, and hardware-software co-design for efficient deep learning systems. I am particularly interested in spike-aware training accelerators, Spiking Transformers, many-core neuromorphic systems, sparse attention operators, and energy-efficient AI computing across FPGA, ASIC, and commercial NPUs.
Before and during my Ph.D. study, I worked on several hardware-oriented AI computing projects, including FPGA-based Spiking Transformer training accelerators, many-core SNN training architectures, floating-point arithmetic IP design, and a 28 nm stereo depth co-processor ASIC.
📖 Educations
- IELTS: 7.0, with 7.5 in reading, 7.5 in listening, 6.5 in speaking and 6 in writing.
- 2023.09 - Present, Ph.D. Student, Microelectronics Science and Engineering, Southern University of Science and Technology and Pengcheng Laboratory.
- 2019.09 - 2023.06, B.Eng., Microelectronics Science and Engineering, Southern University of Science and Technology. GPA: 3.7 / 4.0.
🔥 News
- 2026: Started research on sparse operator optimization for large-model inference on Huawei Ascend NPUs.
- 2026: 🎉 One first-author paper is under review at MCSoC 2026 on communication-aware placement optimization for many-core SNN training.
- 2026: 🔥 One co-author paper published in Nature Communications on SNN training architecture on five FPGAs for federated learning.
- 2026: 🎉 One first-author paper accepted by IEEE NEWCAS 2026 on simulation-guided SNN training co-design with FPGA prototyping.
- 2026: 🔥 One first-author paper published in Microelectronics Journal on spike-aware training architecture for Spiking Transformers.
- 2025: 🎉 One first-author paper accepted by IEEE SOCC 2025 on simulation and dataflow optimization for spike-driven Transformer systems.
- 2025: 🎉 One first-author paper accepted by IEEE ICTA 2025 on reusable floating-point fused-multiply-add processor design.
- 2024: 🔥 One co-authored paper published in IEEE TCAS-I based on a 28 nm stereo depth co-processor ASIC project with the taped-out chip.
📝 Main Publications
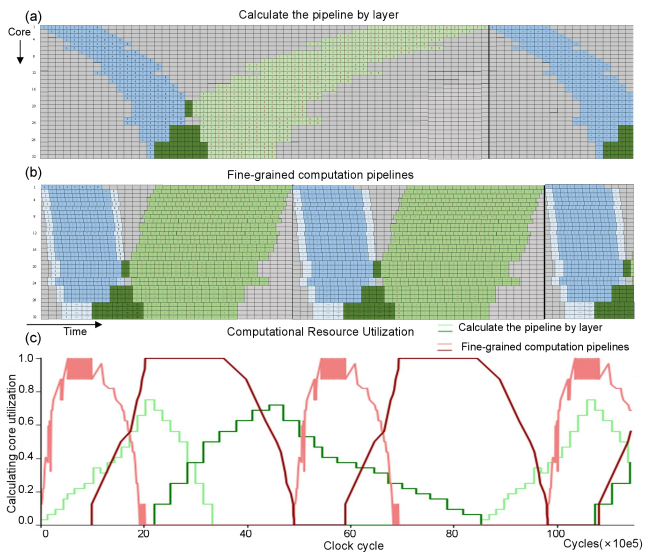
Yunhao Ma, Wanting Wen, Yanyu Lin, Wenjie Lin, Wenxiang Cheng, Boyang Ma, Xiang Li, Wanyi Jia, Zhengyu Ma, Fengwei An, Xueke Zhu, Yonghong Tian, Huihui Zhou
(under review) IEEE International Symposium on Embedded Multicore/Many-core Systems-on-Chip, 2026.
- This paper optimizes logical-to-physical placement for many-core SNN training systems using graph-based reinforcement learning to reduce NoC communication cost, hop distance, and traffic hotspots.
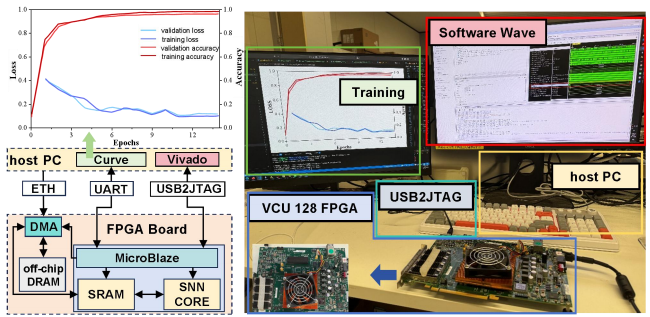
A Simulation-Guided Co-Design Framework for SNN Training with FPGA Prototyping
Yunhao Ma, Wanting Wen, Wanyi Jia, Boyang Ma, Yanyu Lin, Xueke Zhu, Qingyan Meng, Huihui Zhou, Yonghong Tian, Fengwei An
IEEE International NEWCAS Conference, 2026.
- This paper proposes a simulation-guided hardware-software co-design framework for SNN training, covering forward propagation, backward propagation, and weight-gradient computation with FPGA prototype validation. The presentation video provides more information.
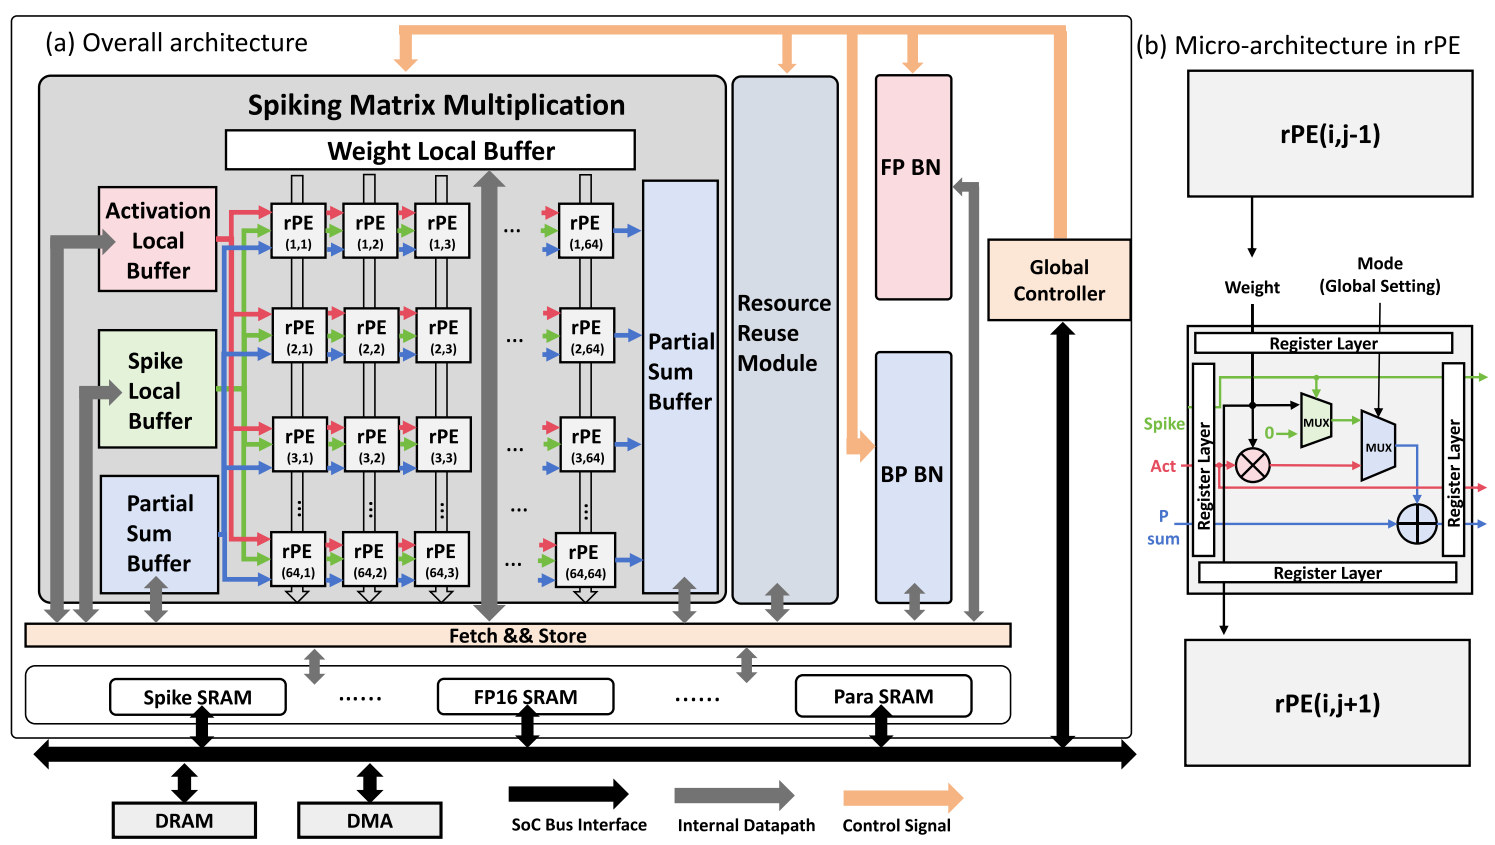
An Energy-Efficient Spike-Aware Training Architecture for Spiking Transformers
Yunhao Ma, Yanyu Lin, Mingjing Li, Puli Quan, Chenlin Zhou, Wanyi Jia, Xueke Zhu, Qingyan Meng, Huihui Zhou, Fengwei An
Microelectronics Journal, 2026.
- This paper presents a spike-aware training architecture and cross-layer simulation framework for Spiking Transformers, supporting FP/BP/WG training with energy-dataflow optimization.
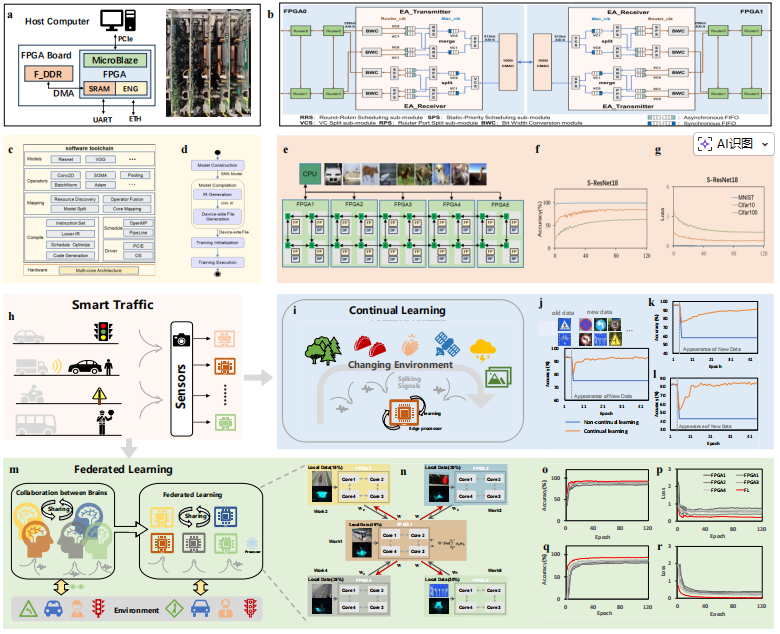
Mingjing Li, Huihui Zhou, Xiaofeng Xu, Zhiwei Zhong, Puli Quan, Xueke Zhu, Yanyu Lin, Wenjie Lin, Xiaosha Li, Dong Wang, Junchao Zhang, Yunhao Ma, Xiaole Cui, Wei Wang, Qingyan Meng, Zhengyu Ma, Guoqi Li, Xiaoxin Cui, Yonghong Tian
Nature Communications, 2026.
- This paper presents a multi-core spike-aware training architecture for SNN and demonstrate it on 5 FPGA borads for ferdal learning.
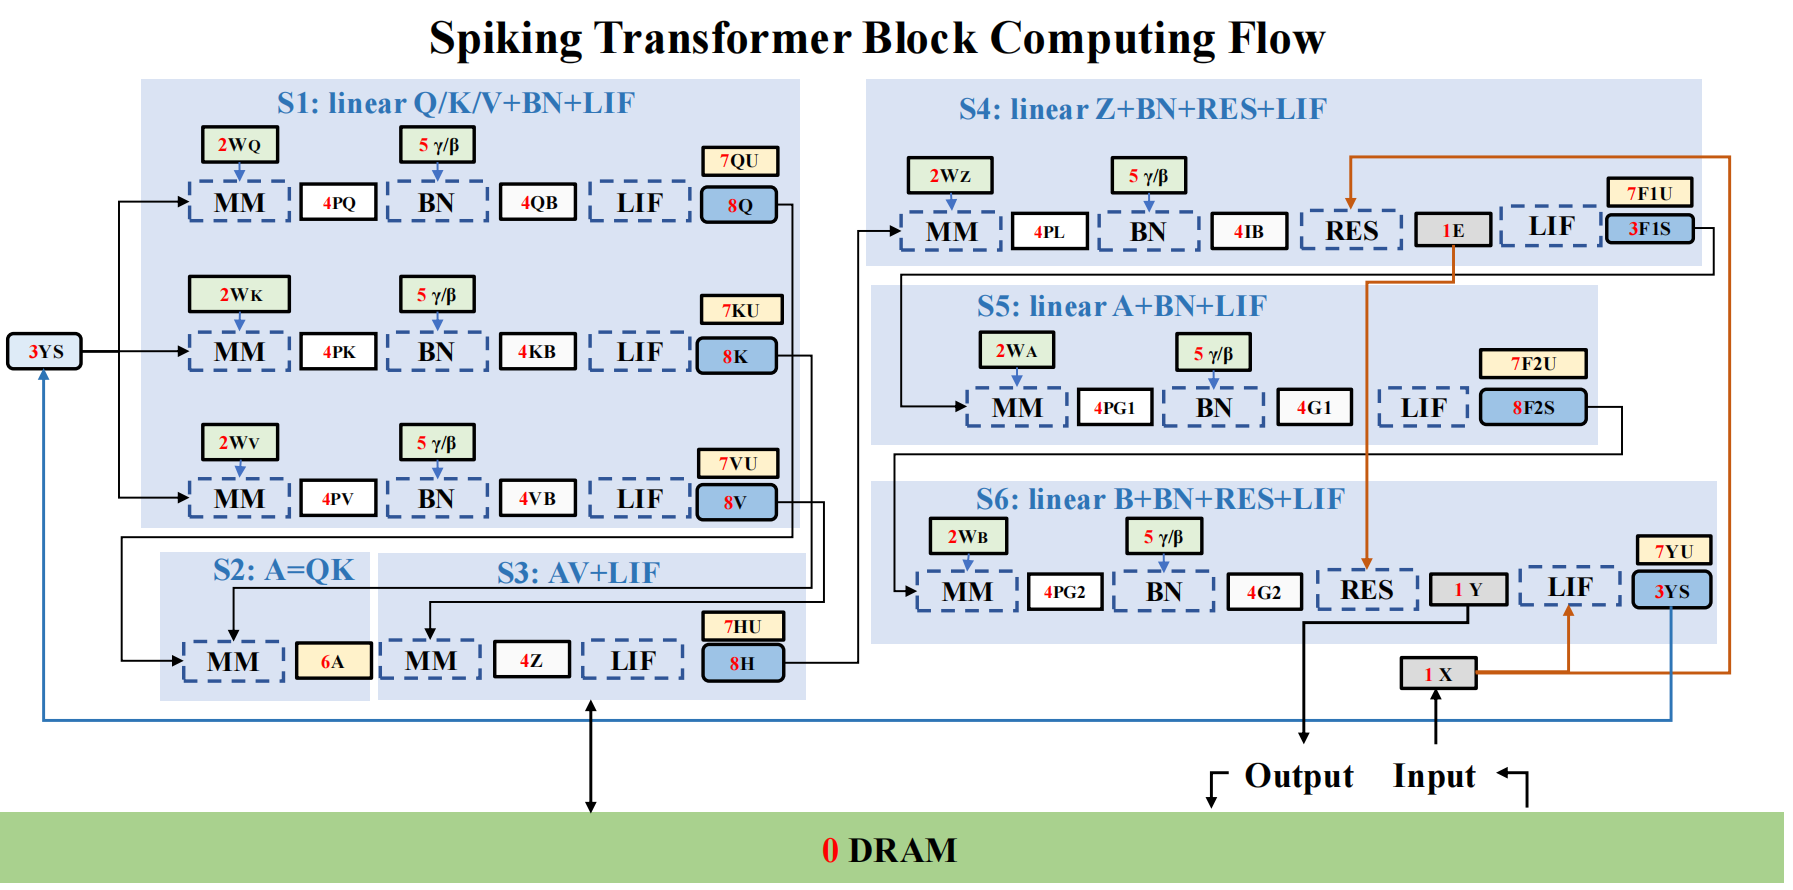
SimST: Simulation Framework for Energy-Dataflow Co-Optimization in Spike-Driven Transformer
Yunhao Ma, Yanyu Lin, Wanyi Jia, Puli Quan, Mingjing Li, Zhiwei Zhong, Fengwei An, Huihui Zhou
IEEE International System-on-Chip Conference, 2025.
- This paper builds a simulation framework for spike-driven Transformer workloads to analyze energy, memory access, and dataflow trade-offs from a hardware architecture perspective. The presentation video provides more information.
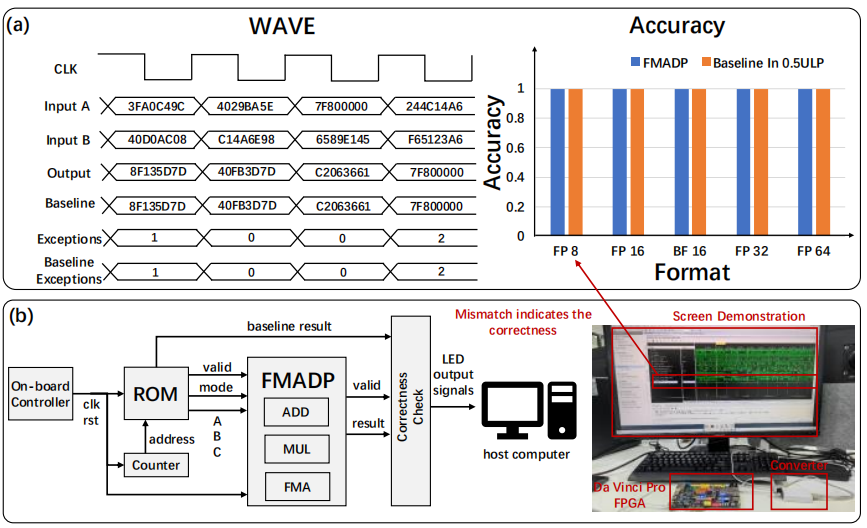
Multiple Precision Floating-Point Fused-Multiply-Add Processor with Hardware Reuse Architecture
Yunhao Ma, Yuhan Wang, Hailin Chen, Runyang Liu, Lei Chen, Huihui Zhou, Fengwei An
IEEE International Conference on Integrated Circuits, Technologies, and Applications, 2025.
- This paper designs a reusable multiple-precision floating-point fused-multiply-add processor to improve hardware resource efficiency for arithmetic IP implementation.
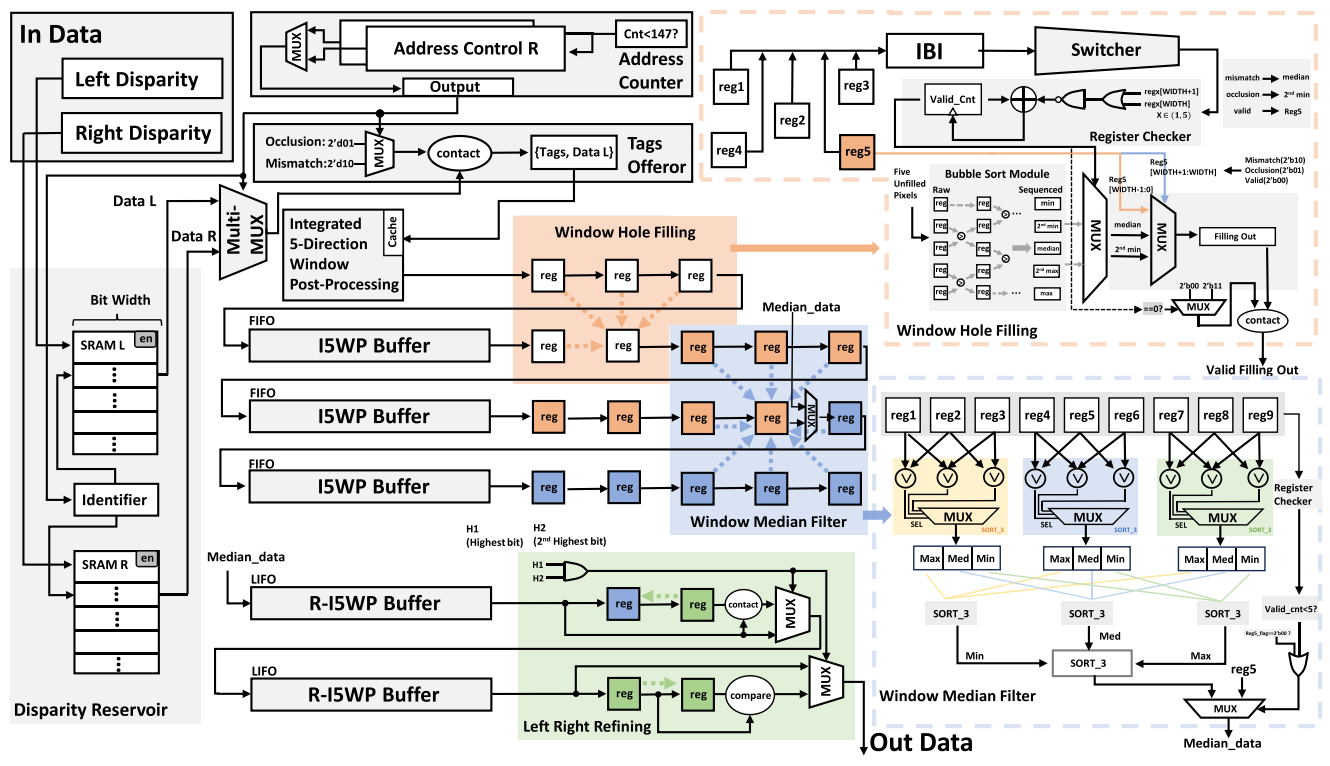
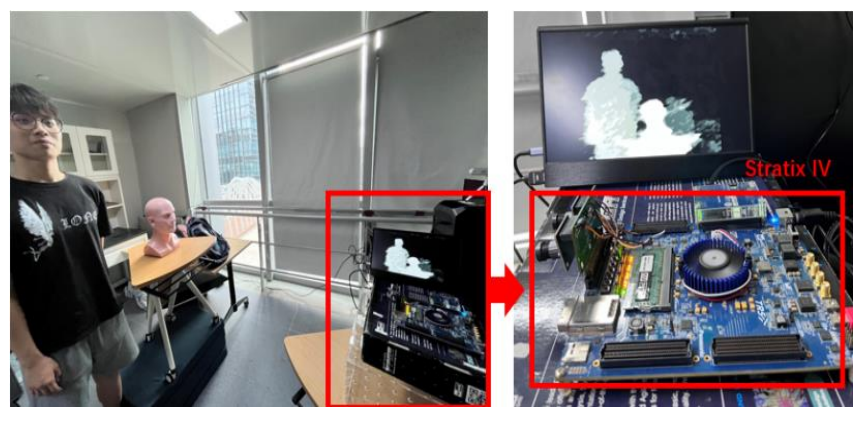
Ke Li, Xiwei Fang , Yunhao Ma, Wenyue Zhang , Pingcheng Dong, Zhuoyu Chen , Lei Chen, and Fengwei An
IEEE TRANSACTIONS ON CIRCUITS AND SYSTEMS—I: REGULAR PAPERS, 2024.
- This paper proposes a nine-direction occlusion filling and pipelined post-processing method to improve stereo matching disparity refinement with sub-pixel estimation.
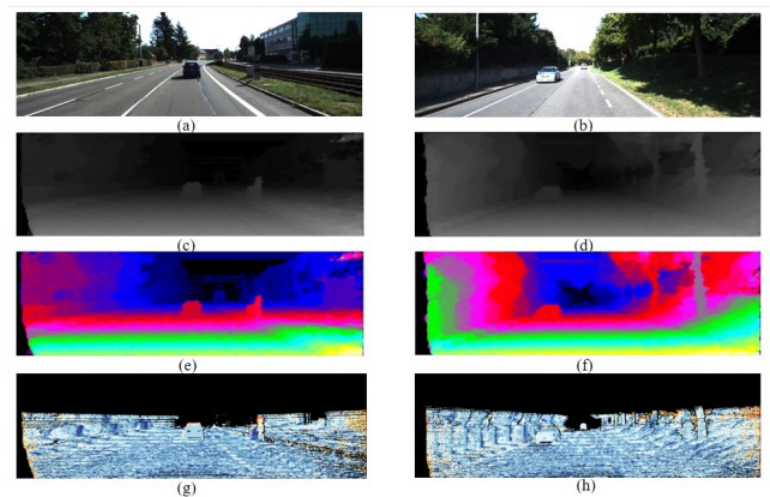
Yunhao Ma, Xiwei Fang, Xinyu Guan, Ke Li, Lei Chen, Fengwei An
Sensors, 2022.
- This paper proposes a five-direction occlusion filling and pipelined post-processing method to improve stereo matching disparity refinement with sub-pixel estimation.
Post-Processing Refinement for Semi-Global Matching Algorithm Based on Real-Time FPGA
Yunhao Ma, Xiwei Fang, Pingcheng Dong, Xinyu Guan, Ke Li, Lei Chen, Fengwei An
IEEE International System-on-Chip Conference, 2022.
- This paper implements real-time FPGA post-processing refinement for the Semi-Global Matching algorithm to improve stereo depth estimation quality. The presentation video provides more information.
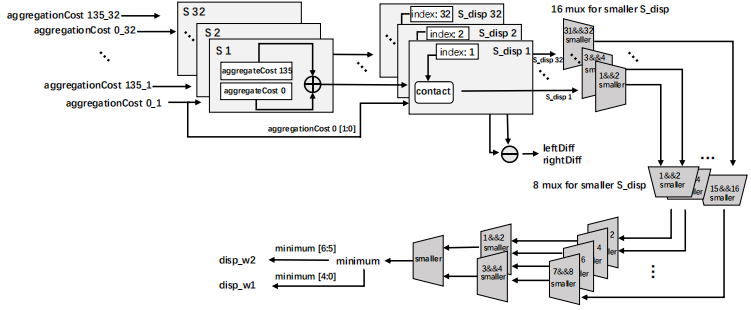
Subpixel Interpolation Disparity Refinement for Semi-Global Matching
Yunhao Ma, Xiwei Fang, Pingcheng Dong, Xinyu Guan, Ke Li, Lei Chen, Fengwei An
IEEE Asia Pacific Conference on Circuits and Systems, 2022.
- This paper develops a sub-pixel interpolation refinement method for Semi-Global Matching to improve disparity-map precision in stereo vision systems.
📝 Collaborative Publications
-
A High-Performance Hybrid Division Algorithm: Combining Additive Iteration, Multiplicative Lookup, and Precision Compensation on FPGA, IEEE International Conference on Electron Devices and Applications, 2025, 5th author.
-
Real-Time_FPGA-Based_Binocular_Stereo_Vision_System_with_Semi-Global_Matching_Algorithm, IEEE International System-on-Chip Conference, 2021, 5th author.
🔬 Research Projects
NPU Sparse Attention Operator Optimization
- 2026.03 - Present
- Optimizing sparse attention operators for large-model inference on Huawei Ascend NPUs.
- Research topics include block-sparse attention, selected attention, sparse index layout, irregular KV access, load balancing, and hardware-aware scheduling.
Spiking Transformer Training Accelerator and Simulator
- 2024.12 - 2026.02
- Proposed a spike-aware training architecture and a software-hardware co-design simulator for Spiking Transformers.
- Covered key operators including matrix multiplication, batch normalization, leaky integrate-and-fire neurons, and residual connections.
- Supported forward propagation, backward propagation, and weight-gradient computation in training with energy-dataflow analysis.
- Validated key components through Verilog/HLS-based FPGA synthesis and implementation.
Many-Core CSNN Training Accelerator Architecture
- 2023.12 - 2025.11
- Participated in the design and implementation of array engines and spike-delivery operators for multi-core CSNN training.
- Focused on floating-point spike-based computation, DRAM traffic reduction, and training-phase mapping on FPGA and many-core architectures.
Floating-Point Arithmetic IP Design
- 2023.04 - 2025.02
- Designed floating-point multiplier, adder, comparator, and fused-multiply-add IPs using Verilog.
- Evaluated resource overhead, pipeline structure, and synthesis frequency against Xilinx Vivado floating-point IPs.
Stereo Depth Co-Processor ASIC Design
- 2021.08 - 2023.04
- Worked on a 28 nm CMOS ASIC for pixel-level Semi-Global Matching.
- Completed DC synthesis, sub-module APR, PrimeTime timing analysis, and Calibre LVS/DRC verification.
- Proposed post-processing optimization modules including sub-pixel interpolation and multi-directional refinement.
- The project was successfully taped out.
🎖 Honors and Awards
- 2024: Huawei Intelligent Foundation Scholarship, Top 10.
- 2023: Outstanding Graduate, School of Microelectronics, Southern University of Science and Technology.
- 2022: APCCAS 2022 Best Paper Nomination.
- 2022: Zhicheng College Innovation and Entrepreneurship Scholarship, Top 2.
- 2021: International First Prize in academic competitions at Southern University of Science and Technology.
- 2021: Global Intelligent Robot Competition, Best Performance Award and Global Champion.
💻 Technical Skills
- Hardware Design: RTL design, Verilog, FPGA, HLS, ASIC flow, DC synthesis, APR, STA, LVS/DRC.
- AI Computing Systems: AI accelerator architecture, SNN training, Spiking Transformer, sparse attention, NPU operator optimization.
- Modeling and Simulation: Energy modeling, dataflow simulation, memory hierarchy analysis, CACTI, Vivado/Vitis HLS, Synopsys, Calibre.
- Programming: Python, C/C++, Verilog, HLS C/C++, shell scripting.
🏠 Internships
- 2023.05 - 2023.08, future vison, China.